A leading European credit servicer manages portfolios of secured non-performing loans acquired from banks. Every portfolio arrives as a wall of paper: mortgage contracts and registrations, guarantees, sale orders, court-appointed appraisals, property registers, statements of liabilities. Due diligence and recovery strategy depend on reading all of it, and the archive had grown to 130 million pages. Hiring to read it was not an option.
The starting point
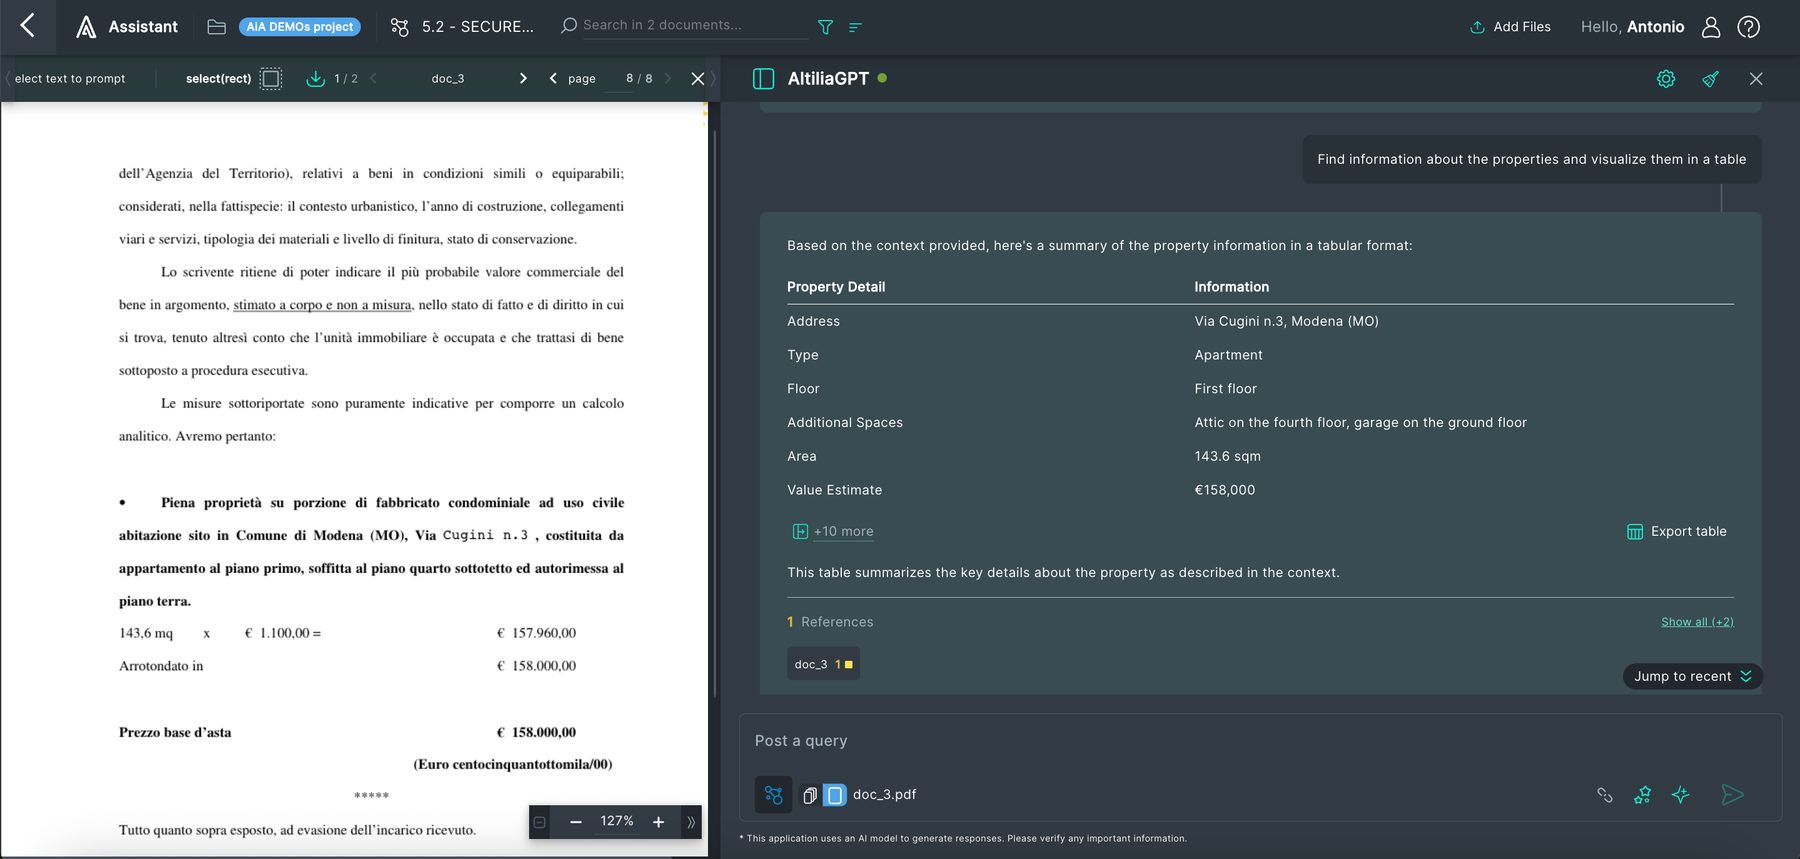
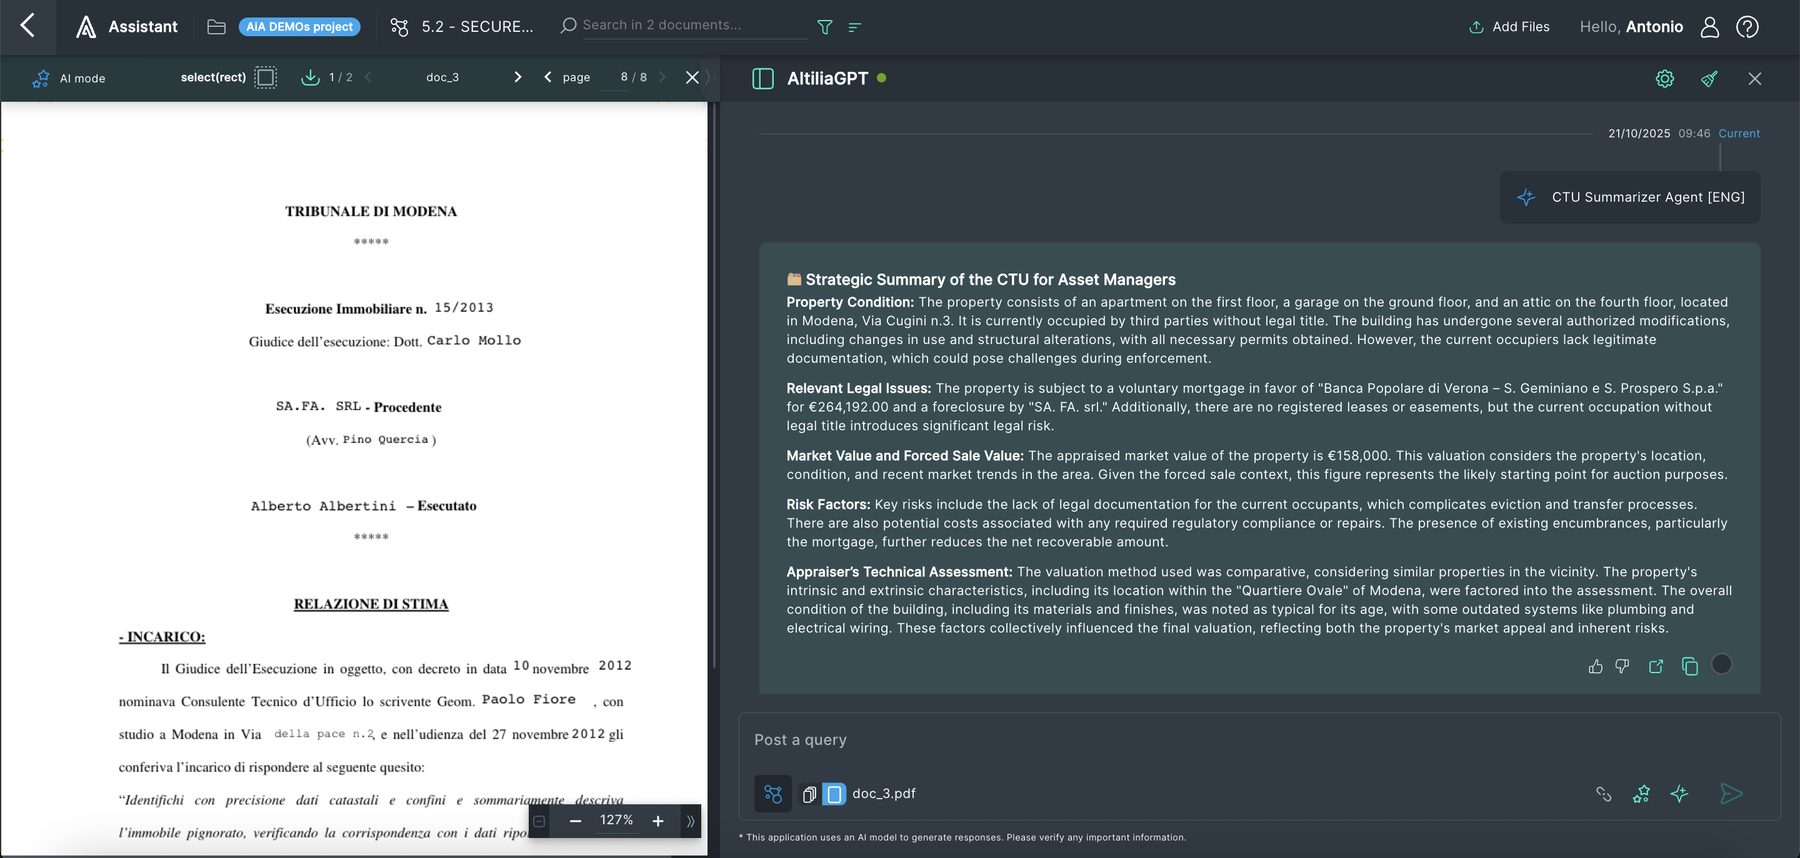
Analysts spent most of their time locating documents and re-keying values. Each case required around 330 datapoints: creditor and debtor identities, guarantors, the complete cadastral description of every property (sheet, parcel, sub-unit, cadastral income), appraisal values, liens and their ranking. The data existed on paper, but not in any system an analyst could query. Recovery strategies were decided on partial information because complete information took too long to assemble.
What the agents did
Altilia deployed a data acquisition agent on the servicer's private infrastructure. Its work happens in four movements.
- Classification. Every page in the archive is assigned to a document type, from mortgage deed to court appraisal, using models tuned on the servicer's own files.
- Extraction. Entities and objects, not just fields: a property is extracted with its full cadastral triple and linked to the appraisal, the lien and the borrower it belongs to.
- Reconciliation. Values found in different documents are compared; conflicts are surfaced with a confidence score and a source hierarchy, so an analyst sees the disagreement rather than a silently chosen value.
- Search. The whole archive becomes a semantic search engine that analysts query in natural language, with regular expressions or with keywords, returning the page as evidence.
The audit
Before going live, the servicer audited a sample of 10,000 documents against manually verified values. Accuracy reached 98.3%. Just as important, the errors were visible: every low-confidence value was already flagged for review, so the audit confirmed that the review queue caught what the models missed.
What changed for analysts
The job moved from locating and typing to deciding. An analyst opens a case and finds the 330 datapoints populated, each with a link to its page. The time saved was measured with the servicer's own business-case methodology: manual effort down by roughly 80%, case preparation ten times faster. Recovery strategies are now decided on complete information, and the semantic search engine answers questions nobody could ask before, such as which properties in a region share the same appraiser or which liens rank ahead of the servicer's across a portfolio.
“Their AI agents work with our own data in a private infrastructure, delivering accuracy and control that no generic AI solution could match.”
Lessons for the next portfolio
- Extract objects, not fields. A cadastral triple that is not linked to its property and appraisal is a number, not knowledge.
- Make disagreement visible. Reconciliation across documents is where the value, and the risk, sits.
- Audit before scale. A 10,000-document sample turned a promise into a number the business could plan on.
- Keep it inside. Running on the servicer's infrastructure removed the data-transfer question entirely.
Key takeaways
- 130 million pages classified and read; 330 datapoints per case, including complete cadastral data.
- 98.3% accuracy on a 10,000-document audit, with low-confidence values already in the review queue.
- Analysts moved from re-keying to deciding; effort down about 80%, preparation ten times faster.
Curious how this would work on your documents?
Related posts
More from the same conversation. All articles
Gartner cites Altilia in the 2026 Magic Quadrant for IDP. Here is how the platform maps to the market it describes.
Four use cases, four mandatory features, sixteen optional ones. Altilia covers them on a knowledge graph, under sovereign deployment, with agents already in production.
Read more →
Symbolic AI and LLMs were never rivals. The ontology is where they meet.
Language models are fluent and ungrounded; symbolic systems are rigorous and empty. Altilia lets agents create and populate ontologies, then reason over facts grounded in them, not just extract data or chat over documents.
Read more →
Why the next era of enterprise AI will be won by architecture, not model size
Bigger models do not fix fragmented intelligence, agent-unready data or missing governance. A semantic layer, an orchestration layer and deployment sovereignty do.
Read more →Send us a message.
Start envisioning the platform tailored for your company. An AI consultant will answer within one business day.